The era of self improvement
A test run should leave the next one better informed.
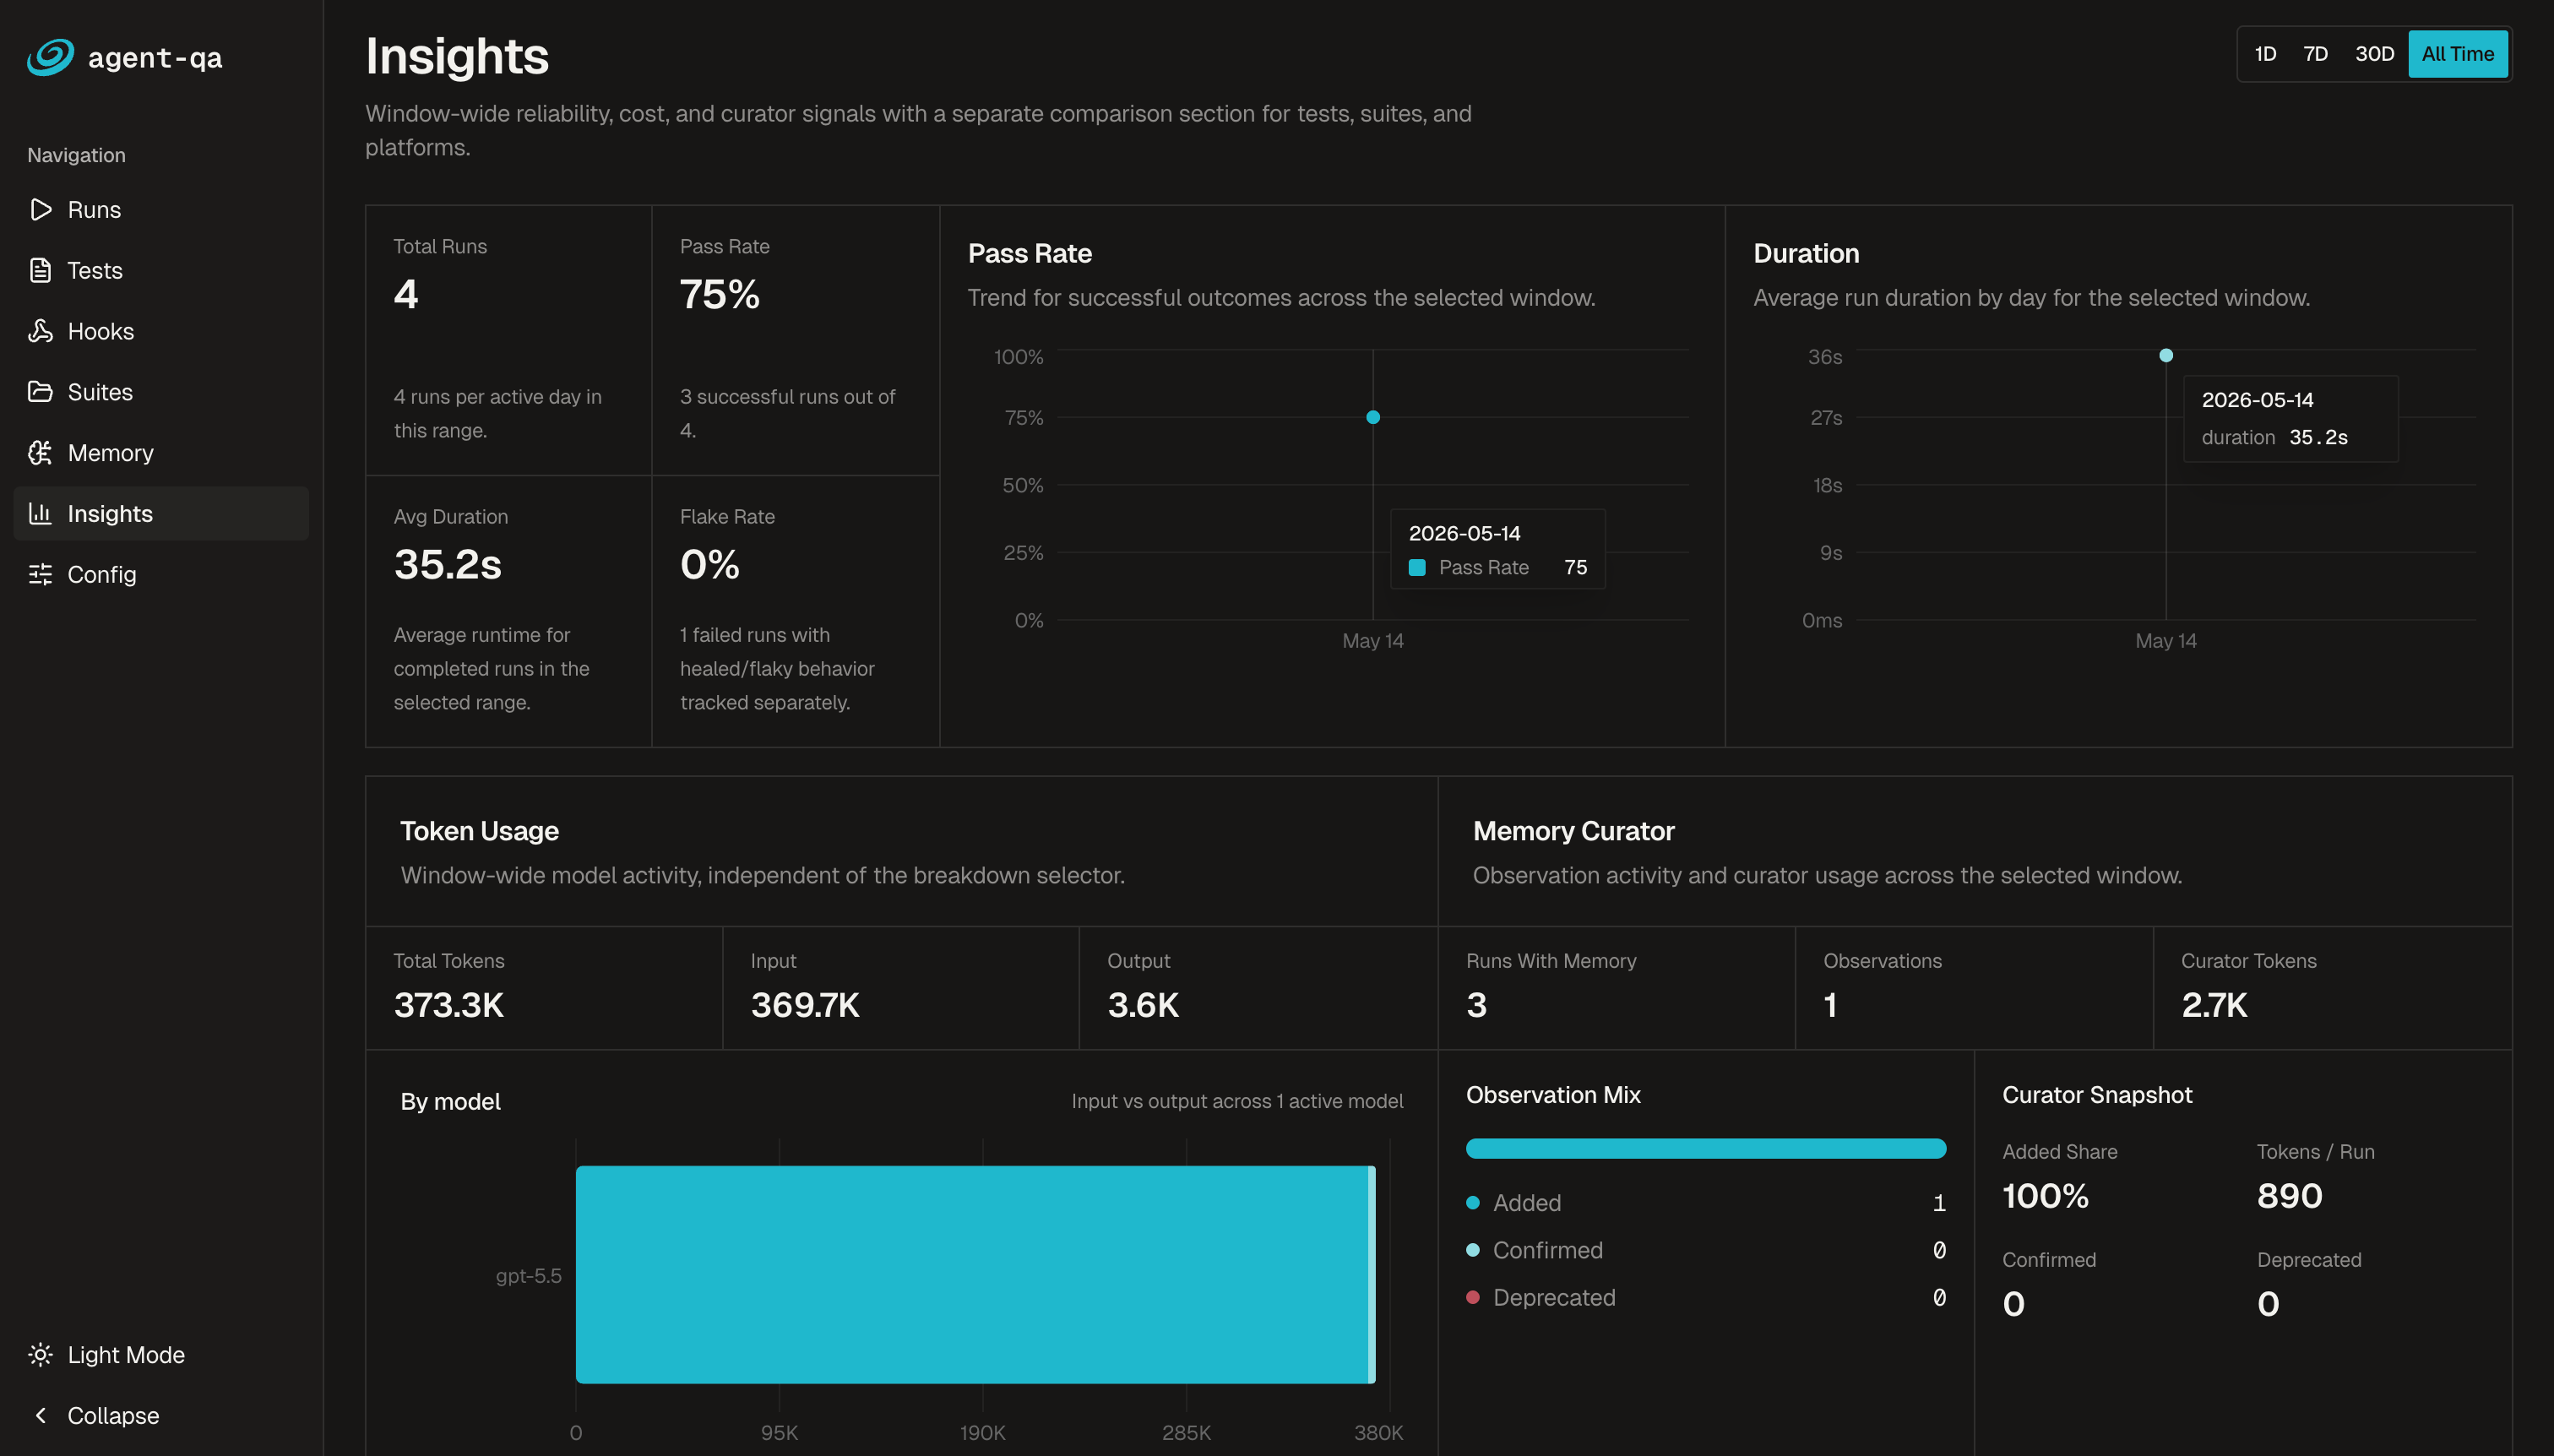
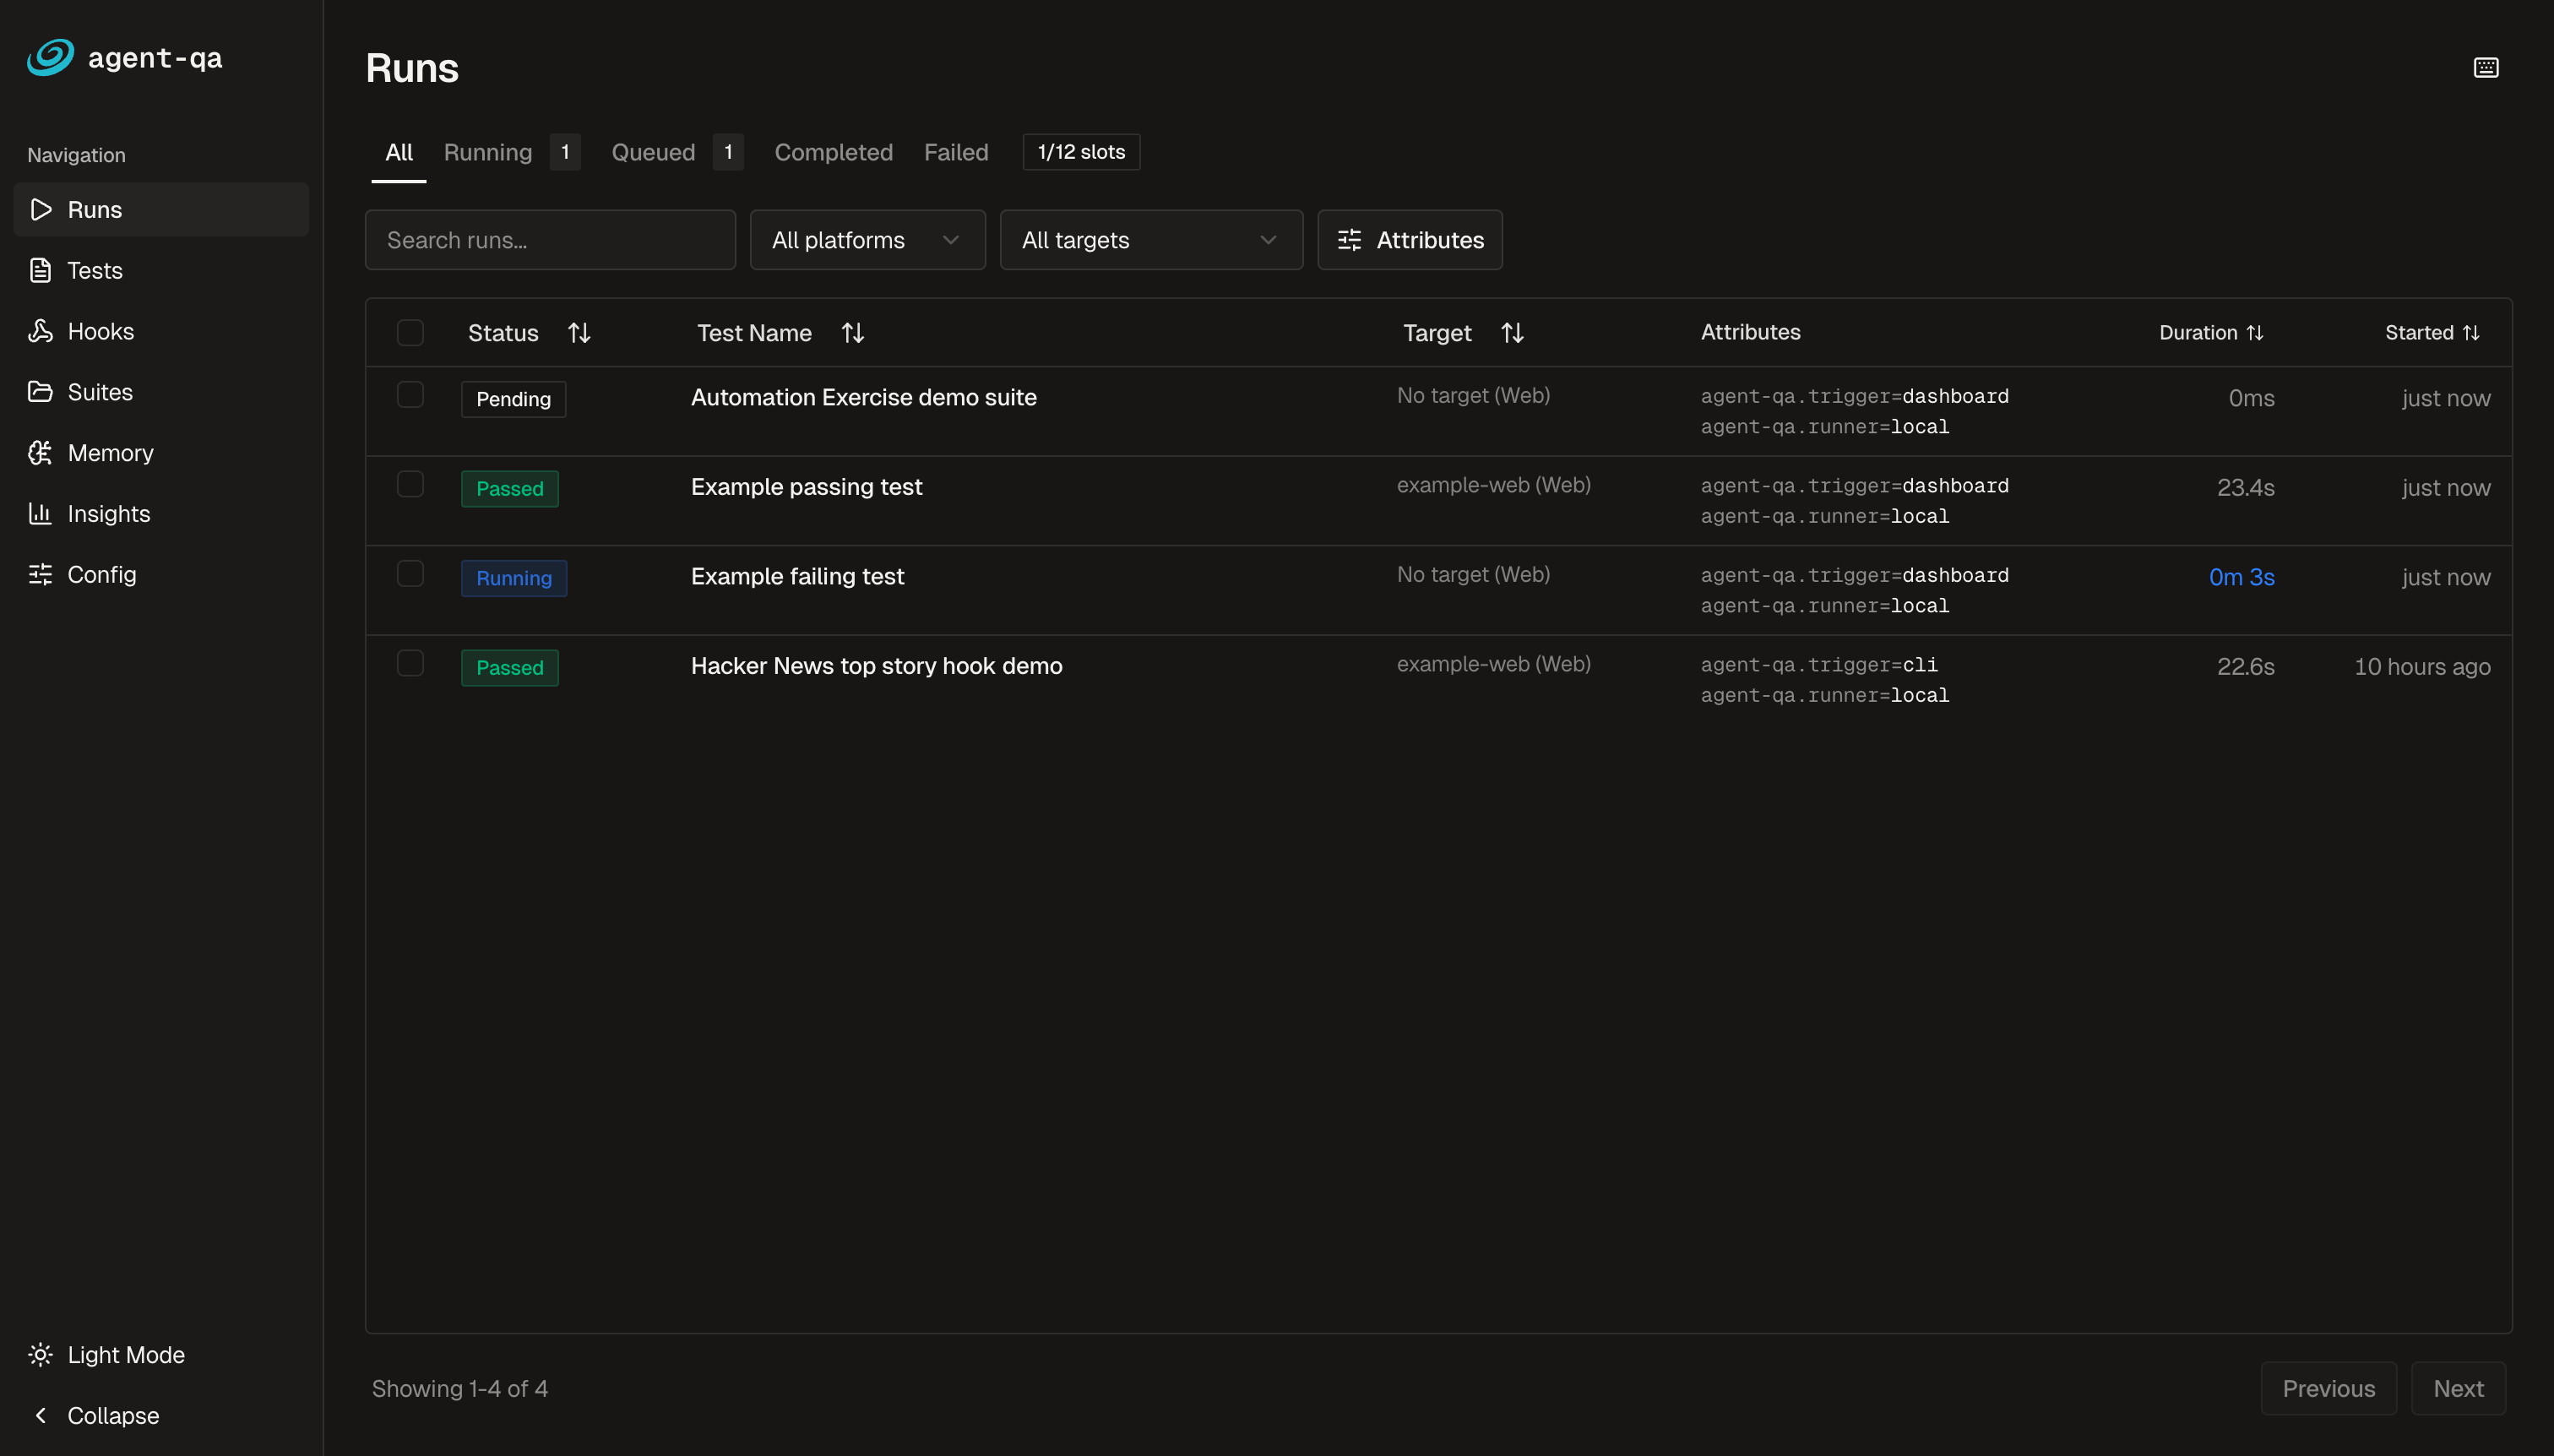
With v2, agent-qa deepens the loop between running a test and learning from it. Completed runs feed failure analysis, memory curation, and improvement proposals, turning execution evidence into context future runs can use. Here is a first look at what is coming.
See the whole failure
Failure analysis looks across the completed run, connecting its steps and artifacts. It helps distinguish an application bug from a test problem or an environment issue, and can leave the verdict uncertain when the evidence does not support a confident answer.
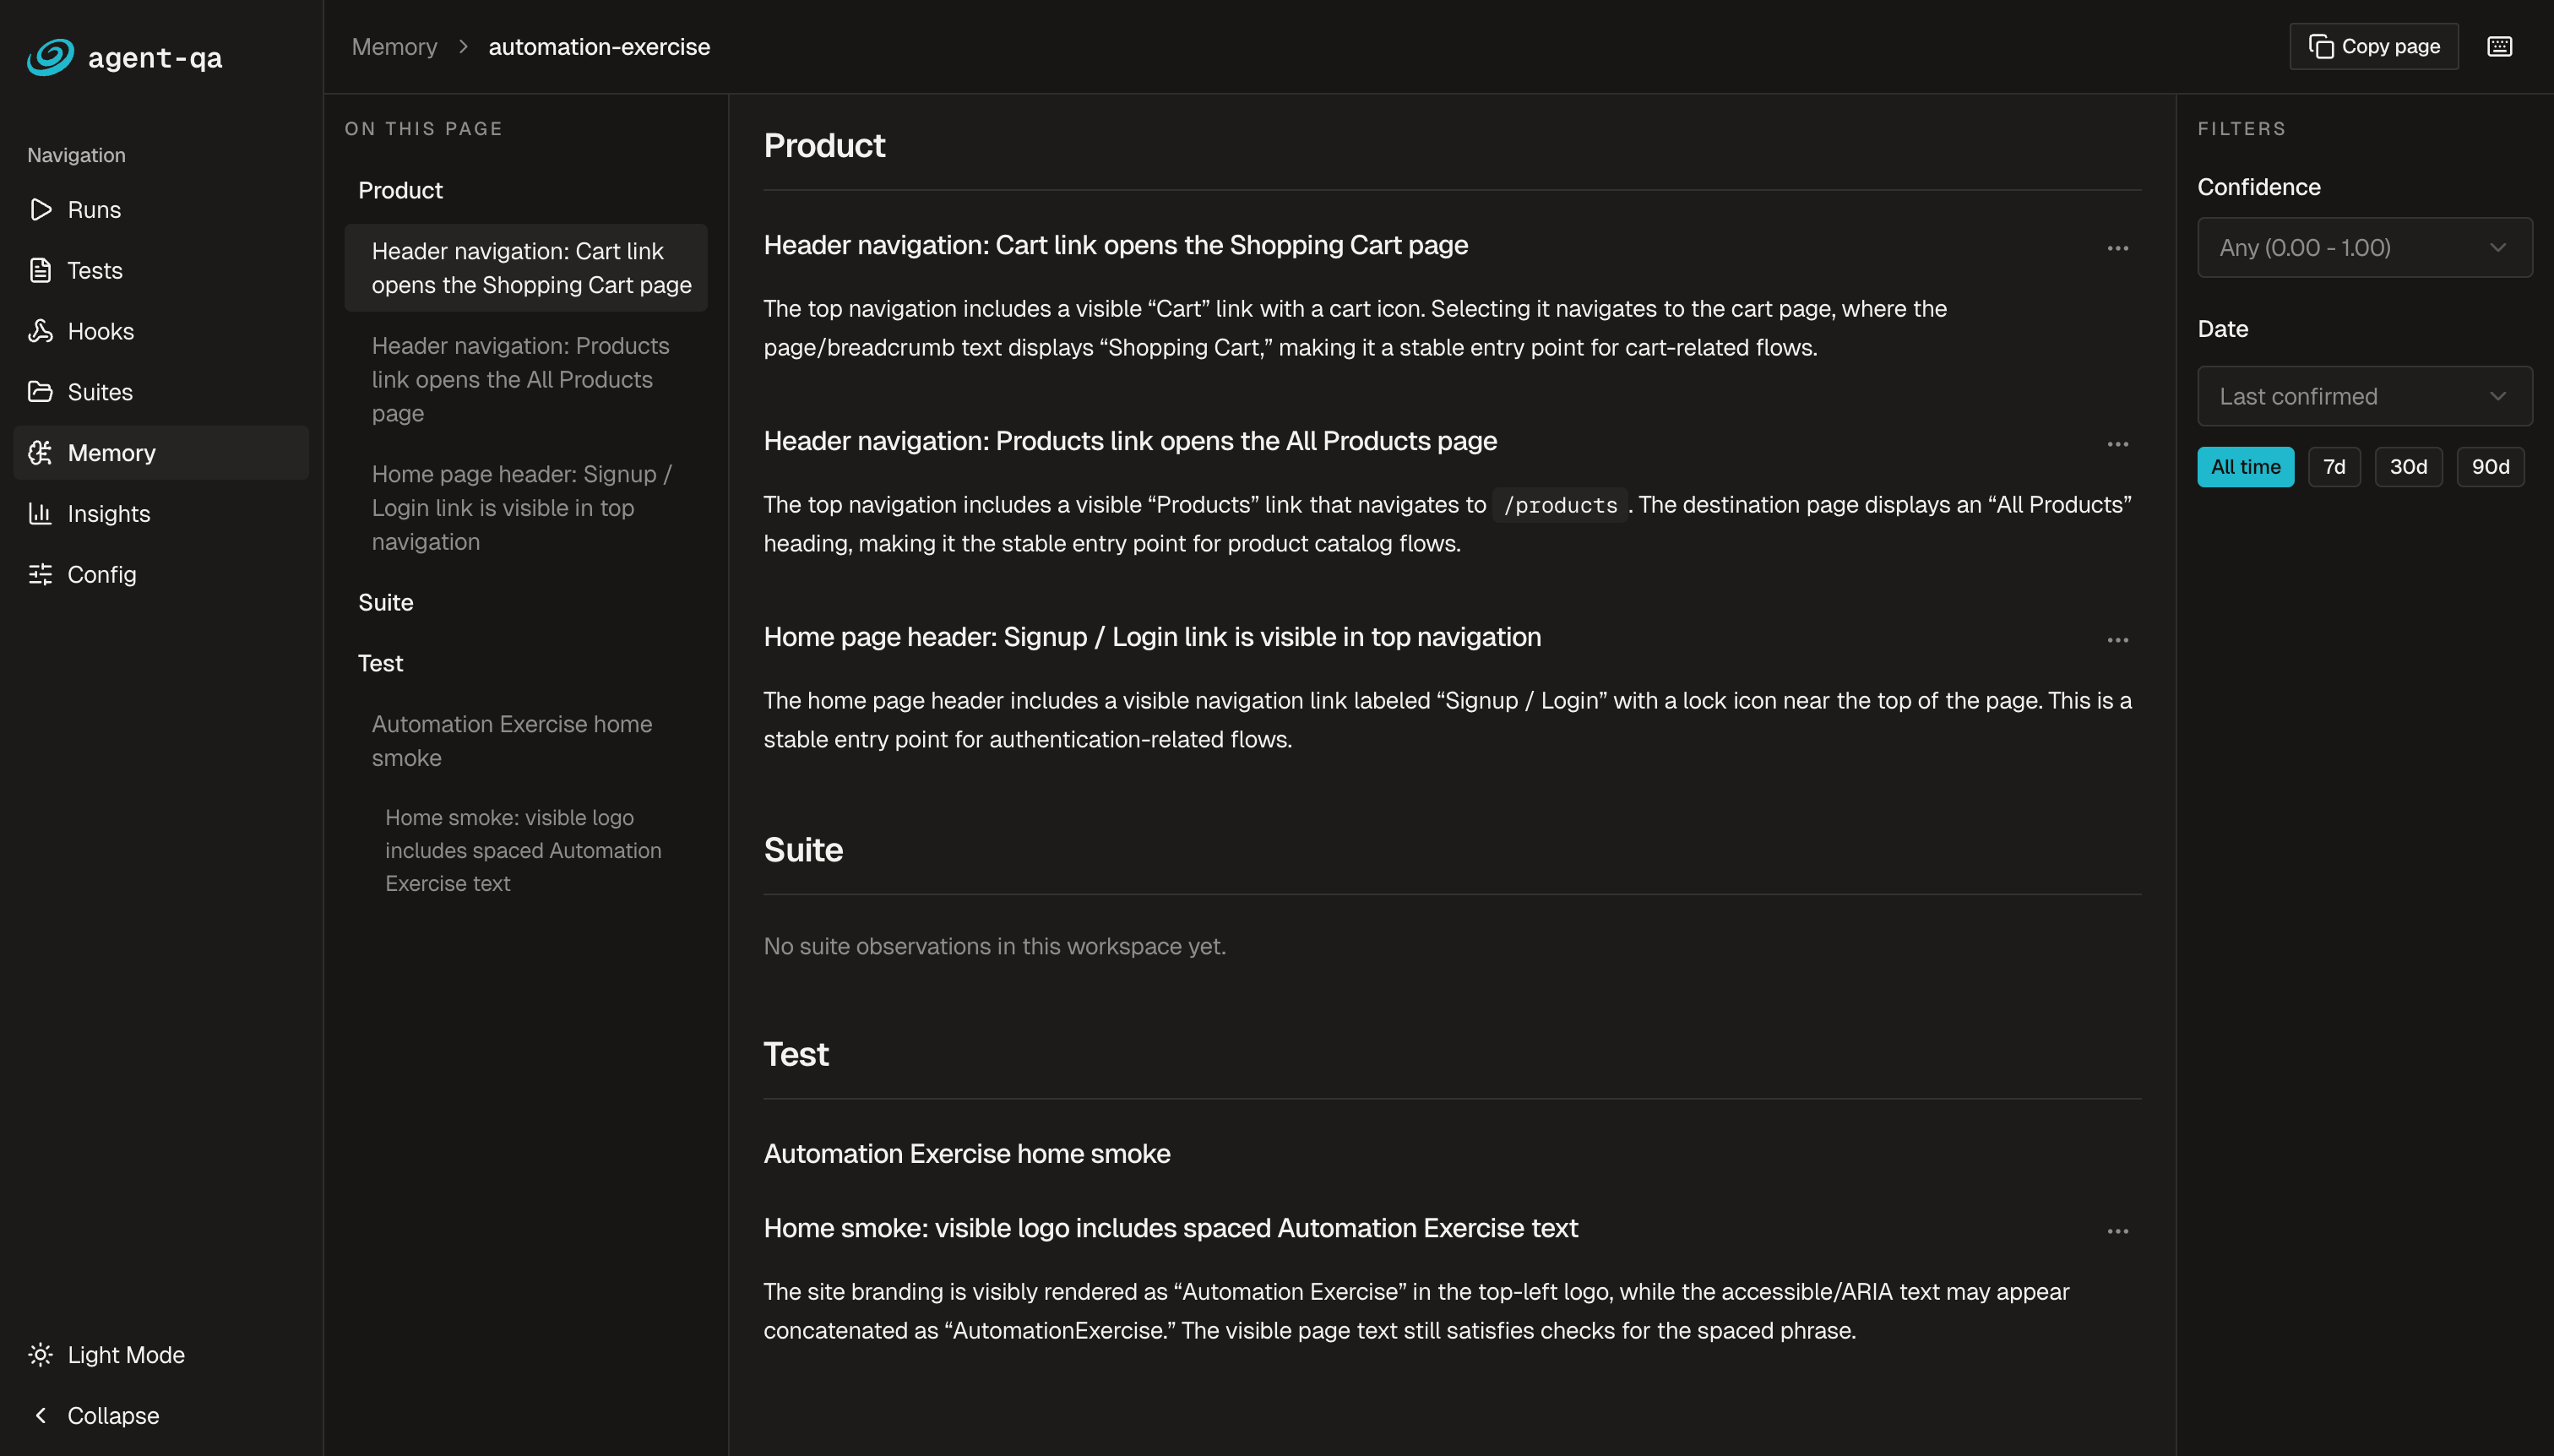
Turn evidence into memory
Observations from a run can become persistent knowledge for future tests. Memory curation retains the run and outcome history behind each change, so useful guidance comes with a record of where it came from. Your corrections to recorded verdicts can also help calibrate the evidence used for learning.
Put proposed improvements to the test
When evaluation is configured, candidate guidance can be replayed against recorded decisions before wider use. Promotion checks and canary evidence help decide whether to advance a candidate, while provenance makes it possible to trace and roll back memory changes.
Keep the learning loop moving
Analysis, curation, and improvement proposals run as durable background jobs. Checkpoints and bounded retries let work recover from interruptions, keeping the learning workflow separate from the test you are running now.